
While the principles discussed in this article apply broadly to reasoning models, the content primarily focuses on OpenAI’s O1 model, based on mentioned resources and own testing.
A big step towards AGI
The landscape of Large Language Models (LLMs) is experiencing a profound transformation. As Sebastian Raschka noted in his recent post, 2024 has witnessed increasing specialization in the field, moving beyond traditional pre-training and fine-tuning approaches. We’ve seen the emergence of specialized applications, including web search LLMs, RAGs (Retrieval-Augmented Generation), topic chatbots, multimodal LLMs, code assistants, reasoning models, agents, and distilled models.
Sam Altman highlighted a significant shift in AI development: while the intelligence improvements from GPT-1 through GPT-4 primarily came from training on larger datasets (with intelligence increasing roughly 100-fold between versions), a fundamental change occurred with the introduction of reinforcement learning and increased test-time compute. This advancement with the release of models like Open AI o1 (Sep 2024), o3-mini (Dec 2024), DeepSeek R1 (Jan 2025) in reasoning capabilities represents a crucial step toward Artificial General Intelligence (AGI). This shift in AI design could mark the transition from “word prediction models” to true “thinking machines.”
OpenAI: “OpenAI o1 ranks in the 89th percentile on competitive programming questions (Codeforces), places among the top 500 students in the US in a qualifier for the USA Math Olympiad (AIME), and exceeds human PhD-level accuracy on a benchmark of physics, biology, and chemistry problems (GPQA).“
OpenAI announced on Feb 12, 2025, that GPT-4.5 will be the last non-chain of thought model they will release.
What is Reasoning/what are Reasoning Models?
Reasoning models represent a refined approach to LLMs, specifically optimized for complex tasks that benefit from intermediate steps, particularly in coding and mathematics. These models think, analyze, and explore different solutions before providing an outcome, employing a step-by-step approach similar to human problem-solving.
For example:
- What are the colors of the Belgian flag? – no reasoning required
- If I making $50 per hour and I work 8 hours a day. Every day I have $75 expenditures. How many days do I need to work to have saved enough money to buy a $30.000 car.
Step 1: Calculate Daily Earnings and Savings
· Daily Earnings:
$50 per hour×8 hours=$400\$50 \text{ per hour} \times 8 \text{ hours} = \$400$50 per hour×8 hours=$400 per day.
· Daily Savings:
$400−$75=$325\$400 – \$75 = \$325$400−$75=$325 per day.
Step 2: Determine the Number of Days Needed
· Total Amount Needed: $30,000
· Days Required:
$30,000$325≈92.31\frac{\$30,000}{\$325} \approx 92.31$325$30,000≈92.31 days
Since you can’t work a fraction of a day, you’ll need to round up to the next whole day.
Final Answer:
You need to work 93 days to save enough money for the $30,000 car.
While traditional LLMs can handle basic reasoning tasks, their approach differs significantly from dedicated reasoning models. Traditional LLMs typically provide direct answers without showing their work, though they can be prompted to show their reasoning process. This is a key distinction from regular LLMs, reasoning models inherently incorporate chain-of-thought processes without explicit prompting, while traditional LLMs require explicit prompting to show their chain of thought (like asking them to “think step by step”). Reasoning models naturally break down problems into intermediate steps and show key parts of their thought process.
It’s worth noting that models like O1 and O3-mini actually perform more internal reasoning than what’s visible in their outputs – OpenAI has chosen to show only a portion of their reasoning process to maintain clarity and conciseness in responses.
And finally, another way of framing reasoning could be as n33bulz in Reddit (cfr. References) succinctly puts it, “Reasoning models is just a fancy term for an LLM that breaks your prompt into smaller pieces and works its way to the answer one step at a time vs trying to solve a complex problem in one go. They call it “reasoning” model because it kind of resembles how we process complex problems as humans, but it isn’t any more aware than previous models.”
Related Concepts
Reinforcement Learning (RL) plays a crucial role in reasoning models. It enables an agent to learn through environment interaction, receiving rewards or penalties based on its actions. Through RL, models like O1 learn to hone their chain of thought, recognize and correct mistakes, break down complex problems, and attempt alternative approaches when needed.
Meta-prompting is the practice of designing prompts that guide an AI model to generate better responses by structuring its thought process, optimizing output quality, or breaking down complex tasks into smaller steps. It involves giving instructions on how to prompt itself or shaping the AI’s reasoning before it answers. A practical use case is to use a reasoning model like o1 or o3-mini to analyze and describe the resolution workflow and steps required to resolve a problem or create a new software program and give the instruction to execute the steps to one or multiple regular LLMs for faster and cheaper execution.
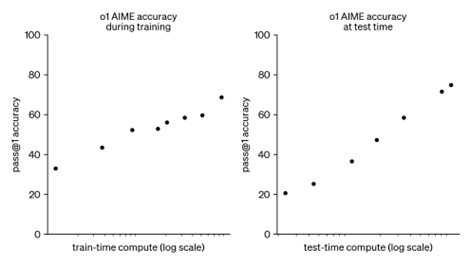
Train-time compute refers to the computational resources (processing power, memory, and time) used during the training phase of an AI model. When we increase train-time compute, we’re essentially giving the model more computational power to process and learn from its training data, allowing it to develop more sophisticated patterns and relationships. This is like how a student might spend more time studying to better understand a subject. In the context of reasoning models, increased train-time compute has been shown to improve their accuracy on complex tasks like the AIME mathematics test, indicating that more computational resources during training leads to better reasoning capabilities.
Test-time compute (also called inference-time compute) refers to the computational resources and time given to an AI model when it’s actually answering questions or solving problems in real-world use. It’s like giving someone more time to think through a problem before they have to give their answer.
For reasoning models, increasing test-time compute means allowing the model to spend more time processing and thinking through its response – exploring different approaches, verifying its work, and refining its answer – before providing the final output. Research has shown that giving reasoning models more test-time compute can significantly improve their accuracy on complex tasks like AIME, even without any changes to the model’s training. It’s similar to how a person might perform better on a math test if given more time to check their work, rather than having to answer immediately.
A practical example is when a reasoning model like O1 solves a complex math problem – giving it more test-time compute allows it to try different solution paths, verify its calculations, and catch potential errors before providing its final answer.
OpenAI: “Our large-scale reinforcement learning algorithm teaches the model how to think productively using its chain of thought in a highly data-efficient training process. We have found that the performance of o1 consistently improves with more reinforcement learning (train-time compute) and with more time spent thinking (test-time compute). The constraints on scaling this approach differ substantially from those of LLM pretraining, and we are continuing to investigate them.”
It looks like test-time compute scaling has a steeper impact on accuracy than train-time compute.
Benefits and Use Cases
Reasoning models excel in several key areas:
- Data Analysis and Scientific Applications:
- Interpreting complex datasets and statistical reasoning
- Experimental design in chemistry
- Biological and chemical reasoning
- Literature synthesis across research papers
- Mathematical and Computational Tasks:
- Solving challenging mathematical problems and physics theories
- Scientific coding and algorithm development
- Computational fluid dynamics models
- Astrophysics simulations
- Complex Problem-Solving:
- Chain of thought reasoning for multi-step problems
- Complex decision-making tasks
- Better generalization to novel problem
These models particularly shine in meta-prompting scenarios, where they can create detailed execution plans with tools and constraints. However, for optimal efficiency, it’s often beneficial to use faster and cheaper models like 4o-mini for execution while leaving the planning to reasoning models.
Limitations and When Not to Use
Despite their advantages, reasoning models come with certain limitations:
- Higher latency compared to traditional LLMs.
- Not optimal for fast and cheap responses. The internal/external reasoning generates a significant amount of tokens, Reasoning Tokens, contributing to the cost. Read more about tokens in LLMs
- May overcomplicate simple tasks through unnecessary analysis.
- Less efficient for straightforward knowledge-based tasks.
- Less hallucinations.
- Writing text in a specific writing style or voice***
Regular LLMs remain better suited for general-purpose text generation, chat applications, summarization, translations and other tasks where speed and cost-efficiency are priorities. They are better optimized for speed, cost-efficiency, and user-friendliness in real-world applications, but struggle with deep, multi-step logical reasoning. They can hallucinate (make up incorrect information).
Key Differences Between Reasoning LLMs and Regular LLMs
|
Feature |
Regular LLM (GPT-4o, Claude 3.5 Sonnet, Gemini 1.5 Pro) |
Reasoning LLM (O1, O3, DeepSeek R1,… ) |
|
Focus |
General text generation |
Explicit reasoning, structured problem-solving |
|
Mathematical Accuracy |
Decent, but may hallucinate |
More rigorous, structured, step-by-step |
|
Logical Thinking |
Pattern-based, heuristic |
Symbolic, multi-step reasoning |
|
Fact-Checking |
Can make factual mistakes |
More accurate due to stepwise deduction |
|
Context Understanding |
Good, but limited over long-range context |
Stronger memory and coherence |
|
Use Cases |
Chatbots, creative writing, summarization |
Scientific reasoning, law, math, long-term planning |
How It Works
The fundamental difference between reasoning and traditional models lies in their approach to problem-solving. Regular models tend to respond immediately with their first thoughts, similar to impulsive responses. In contrast, reasoning models carefully consider problems before responding, exploring multiple possible paths and verifying their answers.
Traditional LLMs function primarily through pattern matching and prediction. When given a prompt, these models look for statistical patterns in their training data to predict what response should come next. They generate responses in a more direct, straight-through manner, like someone who quickly answers based on memorized patterns. While they can perform simple reasoning tasks when explicitly prompted to do so, it’s not their natural mode of operation.
Reasoning models, on the other hand, approach problems more like a methodical problem solver. Instead of generating responses directly, they automatically break down complex tasks into smaller, manageable steps. When presented with a prompt, these models first analyze the problem’s structure, then systematically break it into sub-problems that can be solved sequentially. They verify their work along the way before combining the results into a final answer. This approach is built into their architecture through dedicated neural pathways optimized for step-by-step problem-solving.
To illustrate this difference, consider a simple question like “How many R’s are in ‘strawberry’?” A traditional LLM might quickly pattern match and output a number, sometimes incorrectly, based on its training data patterns. In contrast, a reasoning model would approach this methodically by first visualizing or spelling out the word, then identifying each letter systematically, counting the specific instances of ‘r’, verifying the count, and finally providing the answer along with its reasoning process.
This architectural difference – having dedicated pathways for breaking down and solving problems step-by-step – is what makes reasoning models fundamentally different from traditional LLMs. While both types of models are built on similar underlying neural network technologies, reasoning models are specifically designed to think through problems in a more structured and verifiable way.
What makes this approach particularly powerful is that reasoning models don’t need to be explicitly prompted to show their work or think step-by-step – it’s built into their architecture. This makes them especially effective for complex problems that require careful analysis and verification, such as mathematical proofs, complex coding tasks, or detailed analytical problems.

Four main approaches have emerged for building and improving reasoning models:
- Inference-time (Test-time) Scaling:
- This involves giving models more computational resources and time during actual use
- Includes techniques like chain-of-thought prompting, where models are encouraged to show their work step-by-step
- Can also involve voting strategies where the model generates multiple answers and selects the most common one
- Think of it like giving someone more time to think through a problem carefully
- Pure Reinforcement Learning (RL):
- Models like DeepSeek R1-Zero were trained using only reinforcement learning
- The model learns through trial and error, receiving rewards for good reasoning and penalties for poor reasoning
- Reasoning capabilities emerge automatically through this process
- Similar to how a person might learn from experience and feedback
- Supervised Fine-tuning + Reinforcement Learning (SFT + RL):
- This hybrid approach, used by DeepSeek R1, combines two methods
- Supervised fine-tuning: Training on examples of good reasoning
- Reinforcement learning: Learning through trial and error
- The combination leads to better performance than pure RL alone
- This hybrid approach, used by DeepSeek R1, combines two methods
- Pure Supervised Fine-tuning (SFT) and Distillation:
- Models learn directly from examples of good reasoning
- Can include distillation, where a smaller model learns from a larger one’s reasoning abilities
See in the appendix for 2 simple reasoning examples.
Best Practices for Prompting o1
When working with reasoning models like o1/o3, consider these guidelines:
- Keep prompts simple and direct – straightforward instructions typically yield the best results.
- Skip explicit chain-of-thought prompting – these models can handle multi-step reasoning independently
- Structure complex prompts using delimiters like markdown or XML tags
- <example>wklv pruqlqj wkh idplob zrnh xs dodbphg</example>. Use this example to decode the following sentence in regular English: <sentence>vrphzkhuh ryhu wkh udlqerz wkhuh lv d srw iloohg zlwk jrog</sentence>.
- Demonstrate through examples rather than extensive explanations
- Clearly define your objective**: When you craft your instructions, include precise parameters that describe what a successful response looks like. Encourage the model to continuously refine and iterate its output until it fully meets these specific success criteria.
- ***A post by Ben Hylak and swyx & Alessio in Jan-2025: goes deeper on this, suggesting to wrte actually briefs:
- Start by stating your goal: describe exactly what you want to achieve upfront, opposite to our previous learning with not-reasoning model to tell the model how it should handle the request (e.g. “You are a technical writer, writing as a journalist, …”)
- Specify the output format: elaborate on format and composition of the output
- Establish policies and warnings: mention what the model needs to pay attention to or respect.
- Provide a context dump: dump all information that is relevant in the prompt
- include good criteria of what you consider to be “good” vs “bad”
- ***A post by Ben Hylak and swyx & Alessio in Jan-2025: goes deeper on this, suggesting to wrte actually briefs:
- Regarding markdown formatting**: As of version o1-2024-12-17, API reasoning models will no longer produce markdown-formatted responses by default. If you want the model to include markdown in its output, make sure to add the phrase “Formatting re-enabled” as the first line of your developer prompt.
These practices help optimize the model’s performance while maintaining efficiency and accuracy in problem-solving tasks.
** updated on 21/02/2025 based upon Reasoning best practices by OpenAI
*** updated on 22/02/2025 based upon o1 Skills Issue by Latent Space
Reasoning Examples
Reasoning Example 1
Prompt:
<example>wklv pruqlqj wkh idplob zrnh xs dodbphg</example>. Use this example to decode the following sentence in regular English: <sentence>vrphzkhuh ryhu wkh udlqerz wkhuh lv d srw iloohg zlwk jrog</sentence>.
Response:
Reasoned for 9 seconds
Decoding the cipher
I’m figuring out that the text “wklv pruqlqj wkh idplob zrnh xs dodbphg” is a Caesar cipher with a shift of 3, leading to “this encrypting the channel other to boating”.
Cracking the code
I’m piecing together the Caesar cipher with a shift of 3. Each letter is adjusted backward, resulting in “this morning the family woke up alarmed.”
Decoding the message
Using a Caesar cipher shift of 3, I’m decoding the sentence “vrphzkhuh ryhu wkh udlqerz wkhuh lv d srw iloohg zlwk jrog” letter by letter to reveal a hidden meaning.
Decoding the message
Shifting each letter back by 3 reveals “somewhere over the rainbow there is a pot filled with gold.” This confirms the Caesar cipher shift of 3.
Using the same three-letter shift backward (Caesar cipher) on the sentence:
vrphzkhuh ryhu wkh udlqerz wkhuh lv d srw iloohg zlwk jrog
yields:
· vrphzkhuh → somewhere
· ryhu → over
· wkh → the
· udlqerz → rainbow
· wkhuh → there
· lv → is
· d → a
· srw → pot
· iloohg → filled
· zlwk → with
· jrog → gold
So, in regular English it reads:
“somewhere over the rainbow there is a pot filled with gold.”
Reasoning Example 2
Prompt:
A prison has 10 thieves and 10 killers. A killer is defined as someone that is alive and killed someone. A new thief is locked away in the prison, but he gets into a fight and kills 3 killers. How many killers are there in the prison?
Response:
Reasoned about number of killers in the prison for 10 seconds
A succinct way to see why the answer is 8 is:
1. You start with 10 living killers.
2. The new thief kills 3 of them, so 3 killers are now dead and no longer count as killers (a killer must be alive). This leaves 7 living killers from the original group.
3. The new thief, who is alive and has now killed someone, becomes a killer himself.
Hence, the prison now has 7+1=8 killers.
References
- OpenAI: Learning to reason with LLMs
- Reasoning with o1, with Colin Jarvis
- AI Reasoning Models: OpenAI o3-mini, o1-mini, and DeepSeek R1
- What Are Reasoning Models and Why You Should Care
- Reddit Discussion
- Understanding Reasoning LLMs – Methods and Strategies for Building and Refining Reasoning Models by Sebastian Raschka
- OpenAI CEO: “Super Human Coders By End of 2025” by Matthew Berman
- ** Reasoning best practices by OpenAI
- *** o1 Skills Issue by Latent Space